AI Engineering
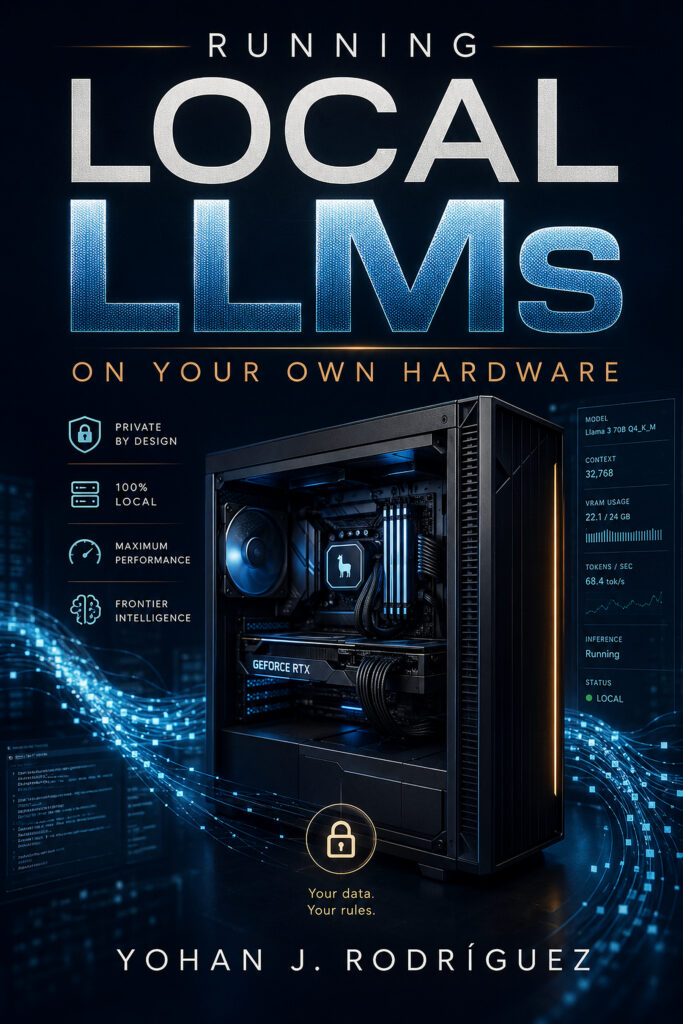
Running Local LLMs on Your Own Hardware
A Practical Guide to Private, Offline, and Self-Hosted Large Language Models
A hands-on guide to downloading, running, serving, and maintaining open-weight LLMs on your own machine.
About this book
Open-weight models now run well on hardware you already own, whether that is a gaming laptop, a workstation with a single consumer GPU, an Apple Silicon Mac, or a capable CPU with enough memory. Running them yourself buys privacy, a cost that does not grow with usage, offline availability, and control over exactly what you depend on.
Running Local LLMs on Your Own Hardware is a practical, hands-on guide to downloading, running, serving, and maintaining those models. It is built around a durable mental model of local inference: how a model uses memory and compute, why memory capacity and bandwidth matter more than raw processor speed, and how that lets you predict what will fit and how fast it will run.
From there the book reads your hardware, chooses a model and quantization, sets up the environment, compares the major inference engines, and runs and diagnoses a first model. It then covers quantization, prompting and sampling, serving an OpenAI-compatible API, retrieval over your own documents, and fine-tuning with LoRA and QLoRA, before closing with benchmarking, scaling beyond one GPU, and security, privacy, maintenance, and troubleshooting.
Examples target Linux first (Debian and Ubuntu with NVIDIA GPUs), with call-outs for Apple Silicon, AMD, Windows through WSL2, and CPU-only setups. Because tools change quickly, the book teaches the principles behind the commands and treats specific flags and model names as snapshots to adapt.
More books
-
AI Engineering
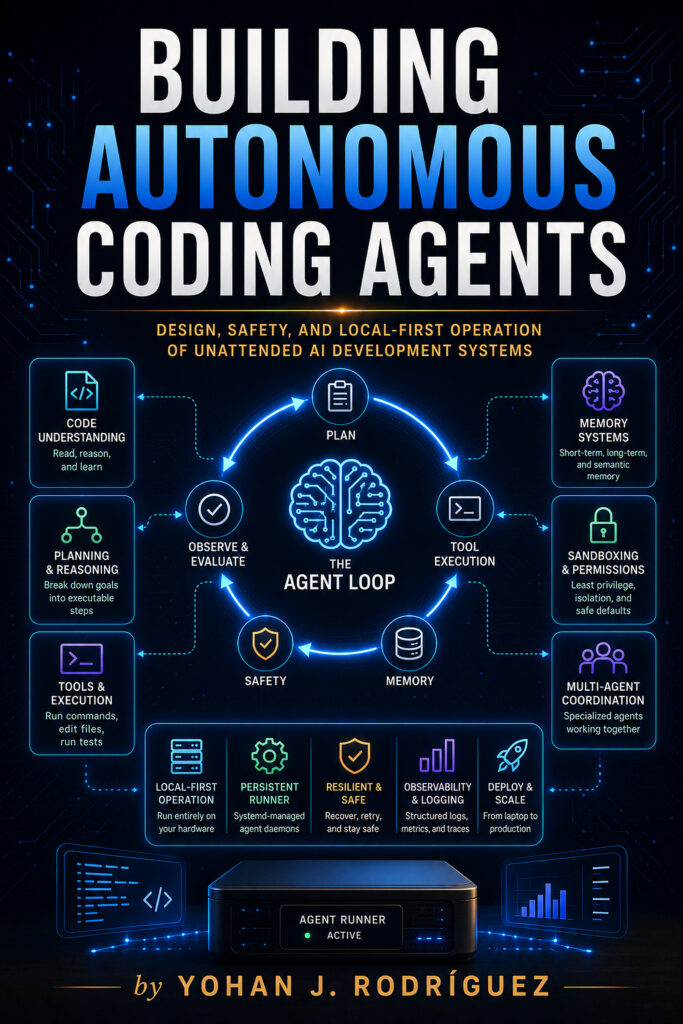
Building Autonomous Coding Agents
Design, Safety, and Local-First Operation of Unattended AI Development Systems
-
AI Engineering
Agentic Coding Harnesses, Compared & Explained
Master Claude Code, Aider, OpenCode, Goose, and Codex — Then Run Them Locally
-
AI Engineering
AI-Assisted Development
Working With Coding Agents